📊 Full opportunity report: The Strategic Importance Of Mixture-of-Experts In Frontier AI Systems on ThorstenMeyerAI.com — validation score, market gap, and execution plan.

Get smart everyday buys delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Mixture-of-experts models are transforming large AI systems by enabling trillion-parameter capabilities at manageable costs. This approach separates memory and compute costs, making frontier AI models more scalable and efficient in 2026.
Mixture-of-experts (MoE) models are now central to frontier AI systems, enabling trillion-parameter models to operate efficiently by separating total memory from per-token compute costs. This innovation is a key factor behind the recent ability to deploy such large models at scale, impacting AI research and industry applications.
Traditional dense transformer models use all their parameters for every token processed, leading to high costs that grow linearly with model size. For example, a 70-billion-parameter dense model requires roughly 70 billion parameters’ worth of computation per token, making scaling expensive and impractical beyond a certain point.
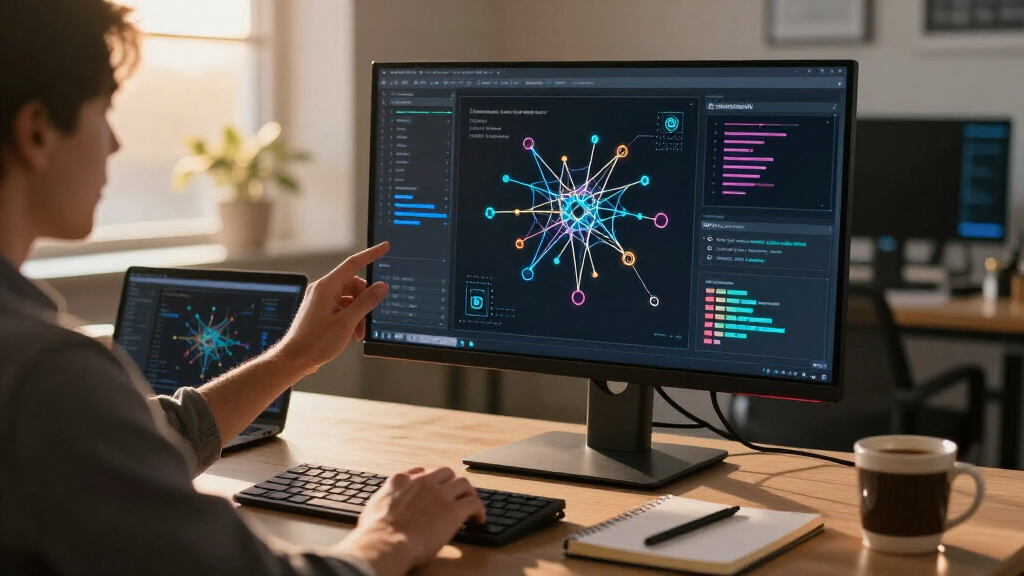
In contrast, MoE models divide their capacity into many smaller sub-networks called experts. During inference, a router selects only a handful of these experts to activate for each token, drastically reducing active computation to a fraction of the total parameters. For instance, Kimi K3’s 2.8 trillion parameters are spread across many experts, but only about 104 billion are active per token, enabling large-scale knowledge without proportional compute costs.
This architectural split allows models to expand total capacity without a commensurate increase in per-token compute, breaking the traditional cost barrier. Experts are not strictly specialized but are learned sub-circuits, with the router dynamically selecting combinations based on input patterns. The entire set of experts must reside in memory, raising total memory requirements, but only a small subset is active at any time, optimizing speed and cost.
Industry adoption of MoE models has been driven by these efficiencies, making trillion-parameter models feasible to serve. The key insight is that total parameters govern memory, while active parameters govern speed, a distinction that many practitioners initially overlook, leading to costly errors in hardware provisioning.
Every serious open model this year quotes two parameter counts instead of one — a huge total and a much smaller active. That split is the single highest-leverage concept for reasoning about how these models run, what they cost, and why they behave as they do.
Instead of one monolith where everything activates for every token, an MoE splits its capacity into many parallel experts. For each token, a small fast router selects only a handful to run. The rest stay dormant.
A dense model welds capability and running-cost together — every added parameter is paid for on every token, forever. MoE breaks the lockstep.
- All 70B run to answer “capital of France?”
- Capability and cost rise in lockstep
- Past a few hundred billion, the per-token bill becomes absurd
- Breadth of a giant model at the per-token compute of a small one
- Grow capability by adding experts, not per-token cost
- The only way trillion-parameter open models are serveable at all
This is the source of the most common expensive mistake in local inference. The two counts are paid to two different pieces of hardware.
The same model, seen through the two-number lens: what fits, and how fast.
Read those two numbers as two questions and you can predict a model before downloading it.
Why Mixture-of-Experts Shapes Frontier AI
The adoption of MoE architectures is a breakthrough for scaling AI models, enabling the deployment of trillion-parameter systems at manageable costs. This approach allows AI systems to have broader knowledge and capabilities without exponentially increasing hardware requirements, thus accelerating progress in AI research and commercial applications.
It also shifts the paradigm from monolithic dense models to modular, scalable architectures, influencing how AI infrastructure is designed and optimized. The ability to balance total memory costs with per-token compute efficiency is crucial for future AI development, making MoE models a strategic foundation for frontier AI systems in 2026 and beyond.
Products Worth Considering

Apple MacBook Pro MPHF3LL/A 14.2-Inch Laptop | M2 Pro 12-Core Chip 16GB Unified Memory 1TB SSD | 19-Core GPU Liquid Retina XDR Display Space

Apple MacBook Air 13-inch Laptop with M5 Chip, 16GB Memory, 512GB SSD, 12MP Center Stage Camera, Touch ID, Wi-Fi 7, Midnight

Apple MacBook Air 15-inch with M5 chip, 16GB memory, 512GB SSD, and Liquid Retina display (Midnight)
As an affiliate, we earn on qualifying purchases.
Origins and Rise of Mixture-of-Experts in 2026
MoE models emerged as a solution to the limitations of dense transformers, which face steep costs as they scale beyond a few hundred billion parameters. Early in 2026, industry leaders recognized that the cost of running dense models at trillion-parameter scales was prohibitive. MoE architectures, which split capacity into many experts and activate only a subset per token, rapidly gained popularity.
By 2026, major AI labs and open-weight communities adopted MoE models, driven by advances in routing algorithms and hardware capable of supporting large memory footprints. These models have become the backbone of frontier AI systems, enabling capabilities previously thought impossible at this scale, such as open models with trillions of parameters that run at feasible speeds and costs.
"MoE models fundamentally change how we think about scaling AI—by separating total knowledge from per-token compute, they make trillion-parameter models feasible and efficient."
— Thorsten Meyer
Unresolved Questions About MoE Model Deployment
While MoE models are proving effective at large scales, it remains unclear how best to optimize expert routing, prevent expert collapse, and ensure interpretability of learned sub-circuits. Additionally, hardware challenges related to memory requirements for storing all experts are still being addressed, and the long-term stability and robustness of MoE models in production environments require further study.
Future Developments in Mixture-of-Experts AI Systems
Research will focus on improving routing algorithms, reducing memory overhead, and enhancing model interpretability. Industry efforts aim to develop more efficient hardware architectures tailored for MoE models, potentially lowering costs further. Expect upcoming large-scale deployments and benchmarks that demonstrate the capabilities and limitations of MoE-based frontier AI systems in 2026 and beyond.
Key Questions
How does mixture-of-experts architecture differ from traditional models?
MoE models split their capacity into multiple experts, activating only a subset for each token, reducing active compute and enabling larger total parameters without proportional cost increases.
Why are mixture-of-experts models considered a breakthrough in AI scaling?
Because they allow models with trillions of parameters to operate efficiently, breaking the cost barrier of dense models and enabling broader knowledge and capabilities.
What are the main technical challenges remaining for MoE models?
Optimizing expert routing, managing memory requirements, preventing expert collapse, and improving interpretability are ongoing challenges.
Will MoE models replace dense models entirely?
Not immediately; however, MoE architectures are increasingly favored for large-scale systems due to their efficiency and scalability advantages.
Source: ThorstenMeyerAI.com